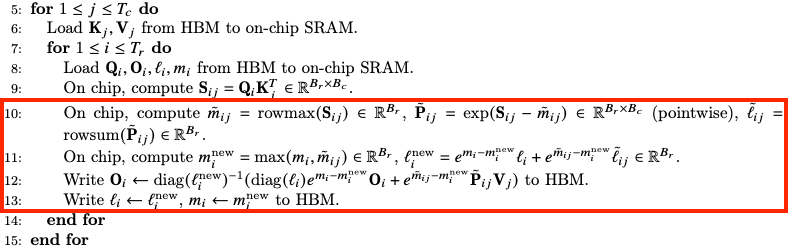
FlashAttention pseudocode for computing tile statistics and updating the accumulated attention output

FlashAttention

Background Frequent HBM Access Creates an I/O Bottleneck in Standard Attention The authors focus on the I/O bottleneck in attention, pointing to the frequent HBM accesses in standard implementations as a major cause. To understand what is going on, we first need to look at the memory hierarchy found in GPUs and most other accelerators. Improving Actual Wall-Clock Time, Not Just Reducing FLOPs The authors note that previous work has tried to reduce the compute and memory complexity of attention, but many of those studies do not report improvements in actual wall-clock time. Their explanation is that these approaches tend to focus on reducing theoretical operation counts while overlooking the overhead of memory access. ...
September 18, 2026 · 13 min · Donghyung Ko

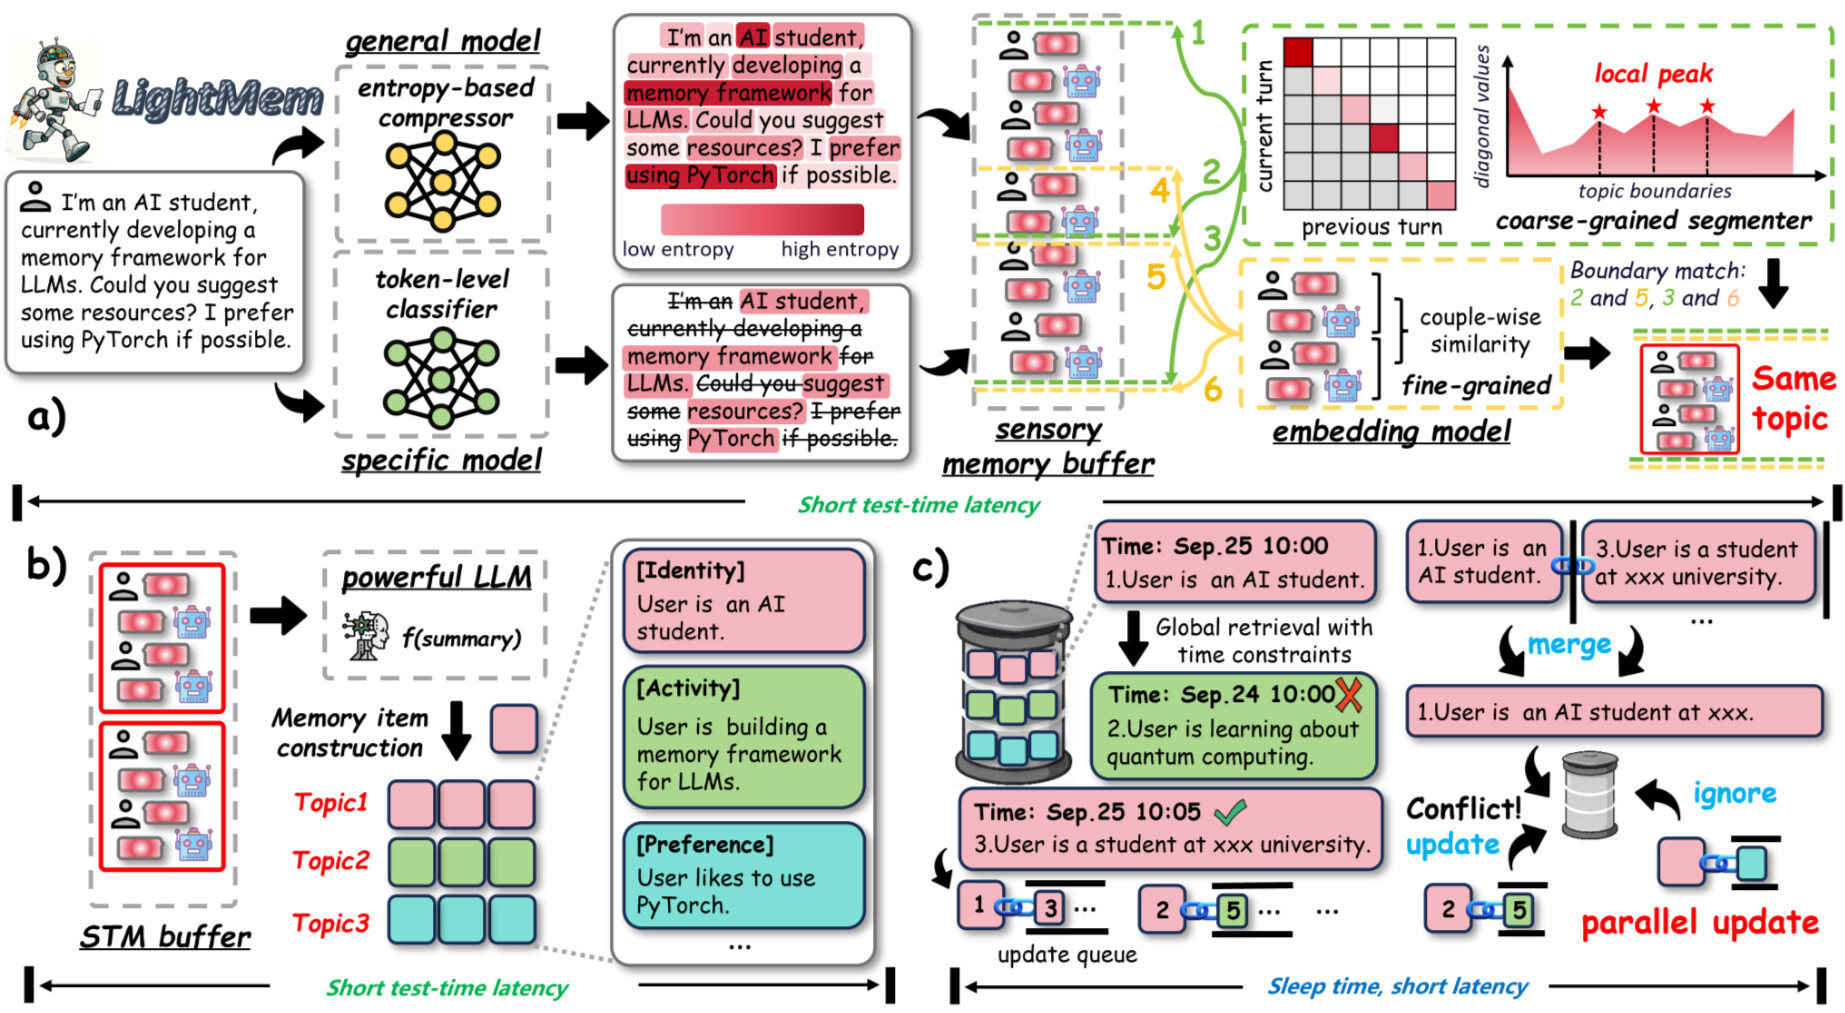
LightMem: Lightweight and Efficient Memory-Augmented Generation

This post summarizes LightMem: Lightweight and Efficient Memory-Augmented Generation. The easiest way to give an LLM agent memory of past conversation is to include the whole history in the prompt every time. That becomes harder to sustain as conversations grow. A long context triggers the “Lost in the Middle” problem, where the model ignores information buried in the middle, and memory systems that re-read the accumulated history on every turn pay for it with higher compute and slower responses. LightMem targets both problems at once. It’s a lightweight memory-generation system that cuts token usage to a fraction of what existing systems need, while outperforming them. ...

April 6, 2026 · 4 min · Donghyung Ko